A high-efficiency inference engine for large models. PerfXLM supports the full family of DeepSeek architectures, heterogeneous hardware, multi-GPU parallelism, and one-click deployment.
It's an excellent combination. It'll build a big model and a super-powered engine.
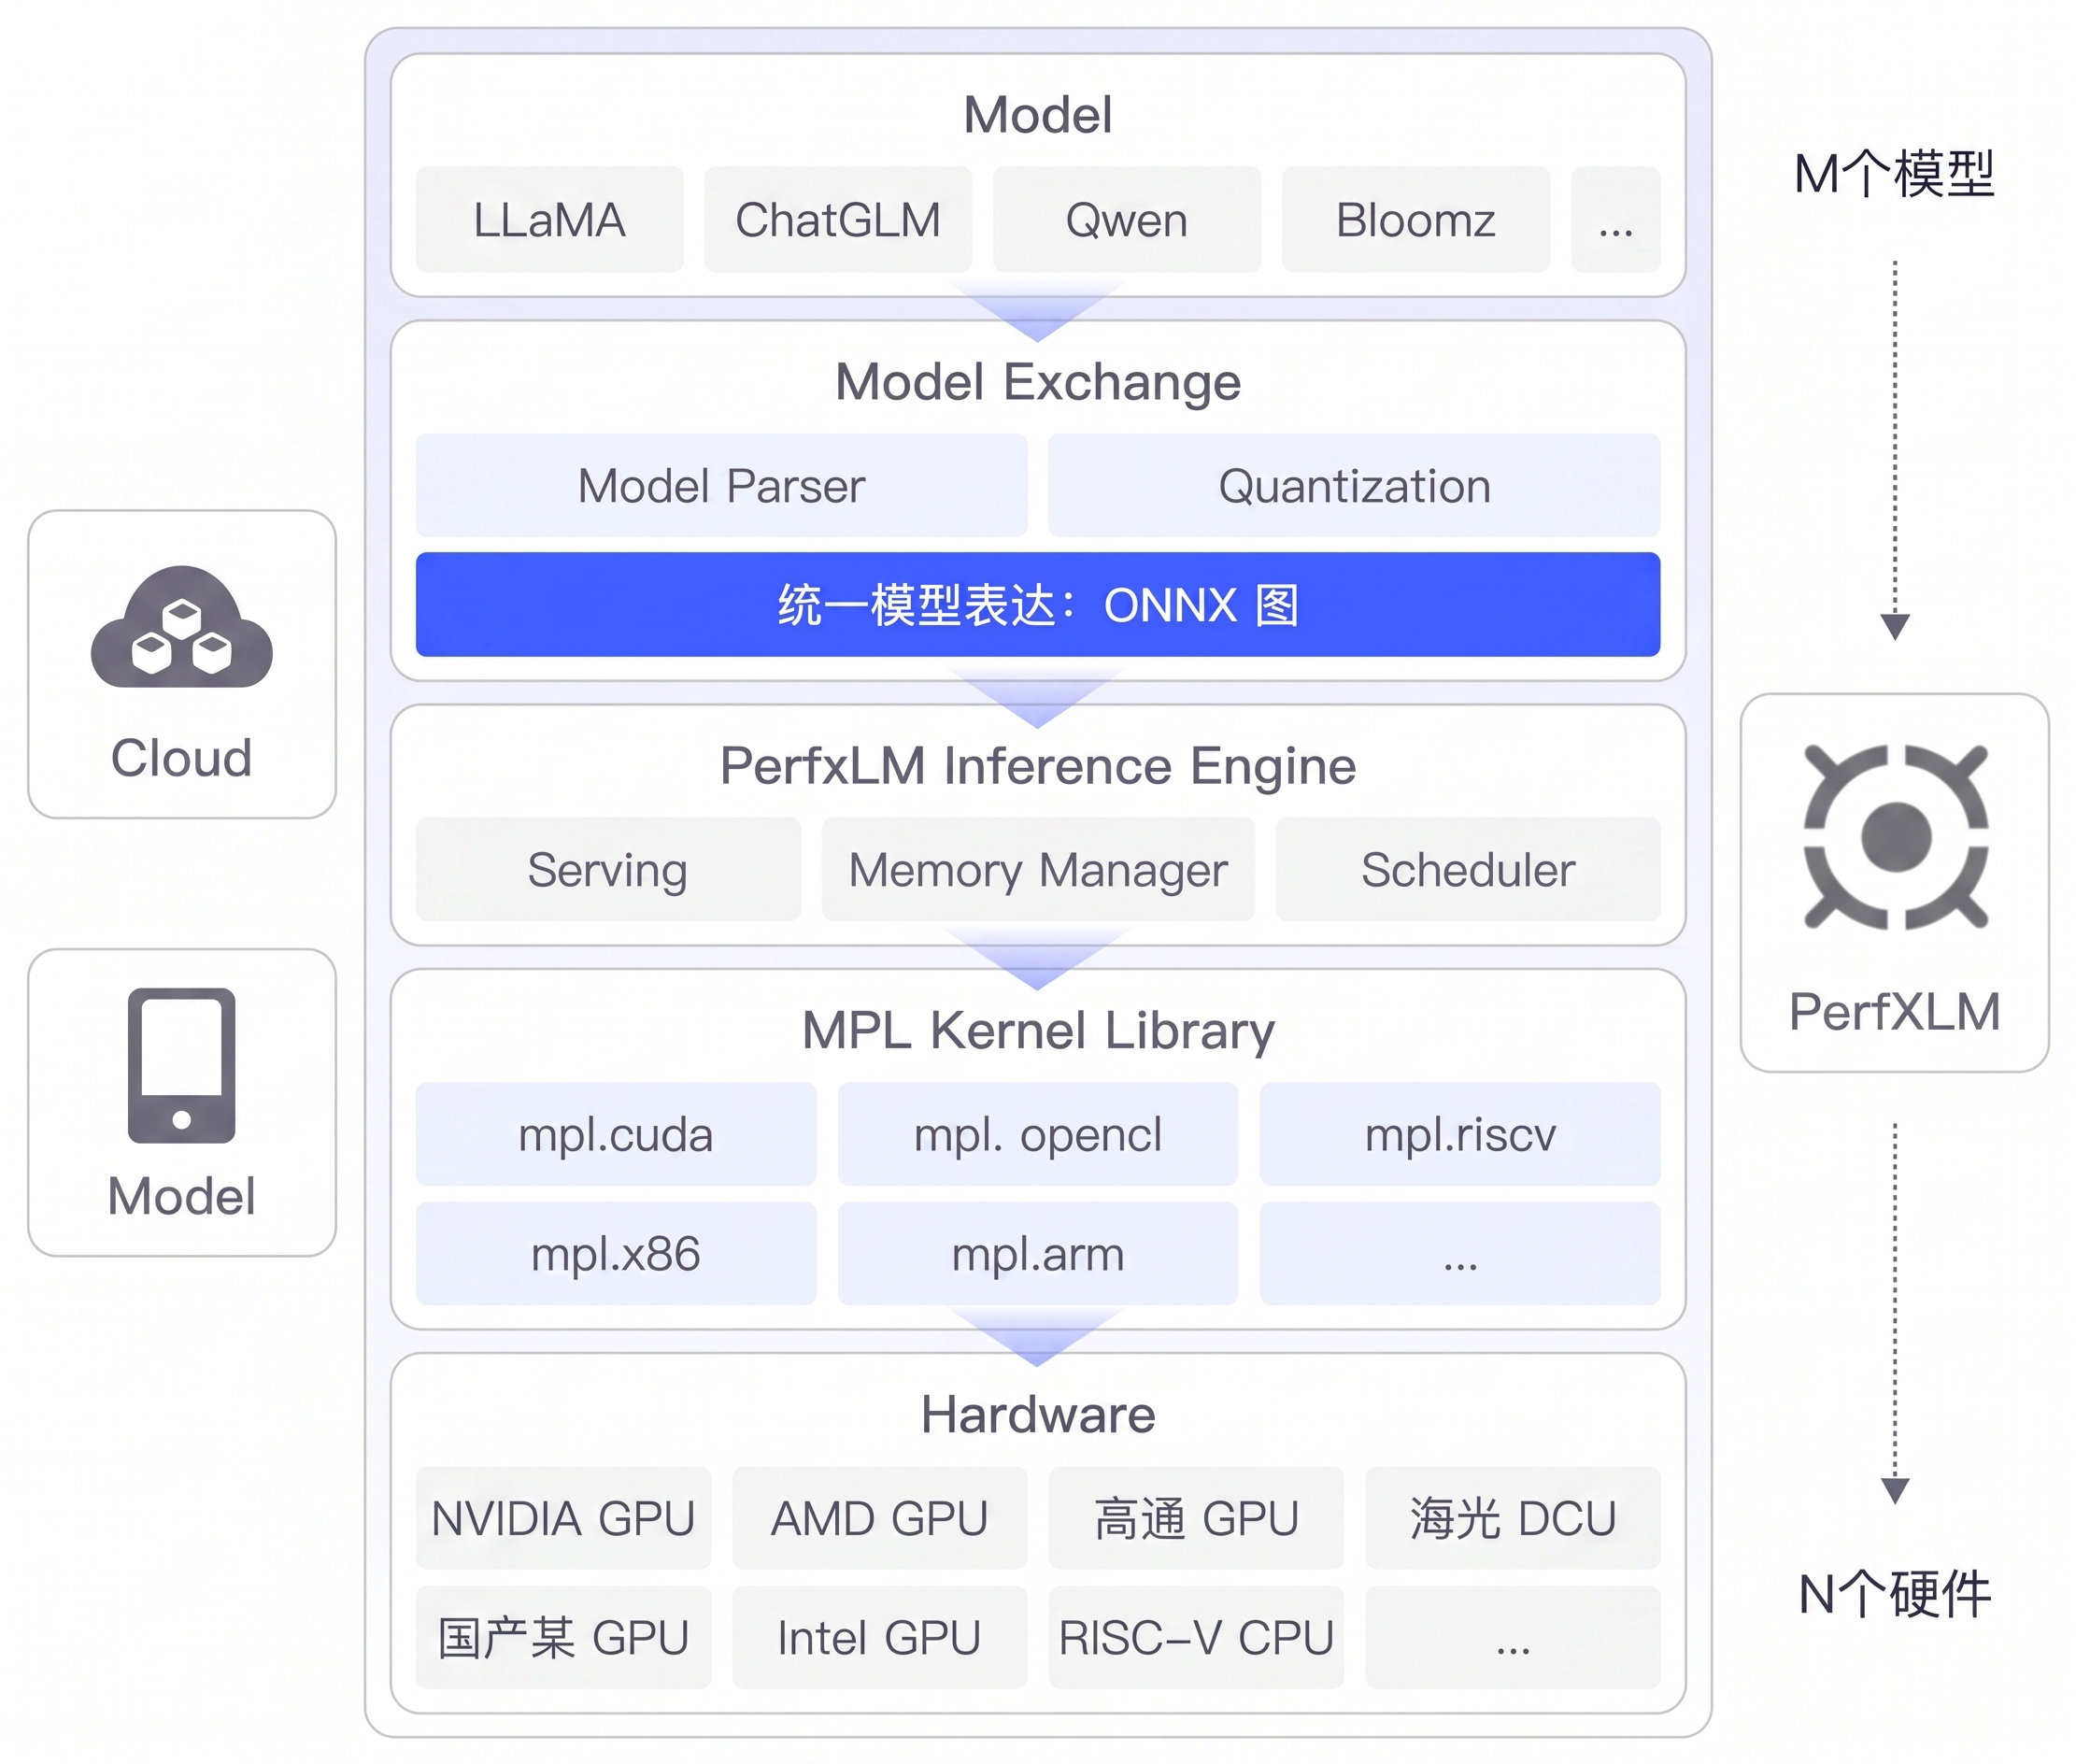
The clouds are one.
There is also support for cloud-side and end-side model reasoning.
Customizing algorithms
Customization optimizes for large model reasoning characteristics.
Multi-isomer platform
Support for various hardware equipment such as GPU and CPU.
DeepSeek support
Full support for distillation models for the DeepSeek-R1 series
Solve the problem of model application and accelerate AI landing
High consumption of model resources
Models such as DeepSeek-R1 have been significantly improved through quantification of multiple model parameters, efficient focus key memory management and integrated high performance algorithms.
Complexity of models and hardware
Innovative three-tier structures, unified model expression, algorithm API definition, have already adapted models such as DeepSeek-R1 to mainstream national production cards.
Complex issue of model integration
The integration of the DeepSeek-R1 series model was greatly simplified by providing API compatible with multi-mainstream frameworks such as Torch and HuggingFace.


 186-0113-7168
 [email protected]